Agentic retrieval on the Mistral Search Toolkit: the five tools
Agentic search means that the model retrieves in several steps instead of once. Mistral's version is a retrieval layer, not a model.
It sits on an index built with the Mistral Search Toolkit, in the cloud or on-premises, and it gives the model five tools that work like file-system operations. The benchmarks below use long, dense material: financial filings and government Treasury Bulletins.
The five Agentic Search tools
| Tool | What it does |
|---|---|
search |
Finds relevant documents across the corpus using the existing index |
open |
Opens a specific document |
navigate |
Moves to a page, section, or region within it |
read |
Retrieves the content at that location |
grep |
Finds a pattern within an open document |
The work is split in two. The index picks the documents that are likely to hold the answer, and the model picks what to inspect inside them and across them. In one-shot RAG, the retrieval step fixes a set of chunks before the model answers.
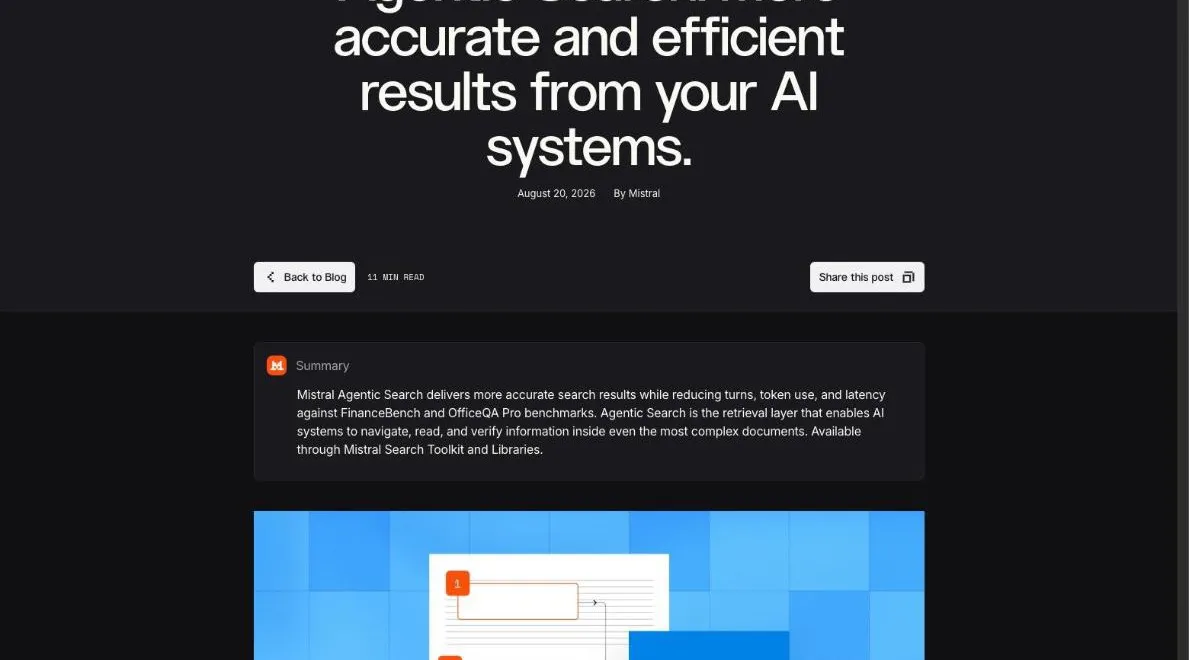
"Agentic Search is the retrieval layer that enables AI systems to navigate, read, and verify information inside even the most complex documents. Available through Mistral Search Toolkit and Libraries."/"Mistral Search Toolkit provides open modules for ingesting, embedding, and indexing critical and complex data in the cloud or on-premises. Agentic Search builds on this index by giving the model five tools that resemble familiar file-system operations:"— from Mistral's announcementView official source →
No fine-tuning: why chunking stops capping RAG accuracy
The five tools need no fine-tuning and no model-specific training. In a one-shot setup, the chunking strategy limits what the model can see. Here the model can open the document and read around a chunk, so retrieval quality follows model capability instead.
The same performance patterns showed up on Mistral's own Medium 3.5 and on GLM-5.2 from Z.ai, which Mistral reads as a sign that Agentic Search is model-agnostic. Because Agentic Search builds on the index, a team that has already tuned its RAG chunking adds the loop on top of that work.
"These tools do not require fine-tuning or model-specific training. As models get better at reasoning and tool use, retrievals get better without infrastructure changes. This is a key property: retrieval quality scales with model capability instead of being capped by your chunking strategy."/"We observe the same performance patterns across first- and third-party models, which indicates that Agentic Search is model-agnostic, and that search quality should improve with new models."— from Mistral's announcementView official source →
Agentic search vs RAG: where one-shot RAG breaks, agentic RAG recovers
One-shot RAG retrieves a fixed set of chunks and asks the model to answer in a single pass. That works when the answer is in a top result.
It falters on long reports, on references that point elsewhere, on comparisons across documents and on checking the evidence. Mistral gives three reasons.
- Retrieval without reasoning. The model has to answer from the first chunks, even when they are incomplete. It cannot decide that it needs another document or section.
- Chunk-level limit. Take a question about a company's tax rate for one quarter. The index can return the right filing, yet it has no way to open it, jump to the table and read the lines around the number.
- No iteration. Many questions need refining the search, inspecting a document, following a reference, comparing sources and trying a new route. One-shot RAG has no step for any of these.
In the RAG vs agentic RAG comparison, the difference is a design choice. One design gives a single retrieval pass. The other gives a loop of tool calls.
"Traditional, one-shot RAG retrieves a fixed set of text chunks and asks a model to answer in a single pass. This works when the answer appears in one of the top results, but falters when the model must navigate a long report, follow references, compare multiple documents, or verify the underlying evidence."/"Retrieval without reasoning: The model must answer from the chunks selected during the initial retrieval, even when they are incomplete or not relevant. It cannot decide that it needs a different document, another section, or more context before responding, which limits the impact of the model's reasoning."— from Mistral's announcementView official source →
Agentic retrieval worked example: OfficeQA Pro and 1953 spending
The loop finds spending for all of 1953 in three tool calls, while one-shot retrieval stops at January to June. The question asks for the total U.S. national defense expenditures across all twelve calendar months of 1953. The Treasury Bulletins in the OfficeQA Pro corpus are organised by fiscal year, not by calendar year.
One-shot retrieval runs one search. It gets ten monthly bulletins framed by fiscal year, finds January to June, and stops without the other six months.
The agentic loop makes three tool calls. The first search returns the same partial year.
A second, reformulated search brings up treasury_bulletin_1954_02.pdf, page 15. Then read pulls Table 3, which lists all twelve months of 1953, and the sum is 44,463. The second search is the step that one-shot RAG cannot take, because it depends on the model seeing that the first results were incomplete.
"search("…1953 November December 1954 to date") → surfaces treasury_bulletin_1954_02.pdf p.15 (Table 3, all 12 months of 1953)"/"read(treasury_bulletin_1954_02.pdf, p.15) → pulls the complete Table 3"/"Sum = 44,463."— from Mistral's announcementView official source →
Agentic search benchmark results: FinanceBench and OfficeQA Pro
In Mistral's own runs, correctness rises from 26.7% to 86% on FinanceBench and from 6.3% to 51.9% on OfficeQA Pro. That is about 3x on FinanceBench and a gain of 45.6 points on OfficeQA Pro. Mistral used the out-of-the-box stack with no tuning, and it calls the results floors, not ceilings.
Correctness, one-shot RAG vs the full loop (Mistral's figures)
The full loop reaches 86% on FinanceBench against 26.7% for one-shot RAG, and 51.9% on OfficeQA Pro against 6.3%. OfficeQA Pro stays near half correct even with the loop.
The two benchmarks
| FinanceBench | OfficeQA Pro | |
|---|---|---|
| Corpus | 368 SEC filings (10-K / 10-Q / 8-K) | 696 U.S. Treasury Bulletins |
| Scale | ~147 pages each, ~53,900 total | ~89,000 pages, scanned |
| Questions | 150 | 133 (the "pro" subset, first pass) |
| Scoring | LLM judge calibrated against human labels | Verifiable numeric answers |
| One-shot RAG to full loop | 26.7% to 86% | 6.3% to 51.9% |
FinanceBench: agentic RAG loop adds ~50 points, navigation ~7
Letting the model search repeatedly adds 47.3 and 52.6 points, and the navigation tools add 8.7 and 6.7 more. The ablation separates the loop from the navigation tools.
Moving from one-shot RAG to a loop that only calls search adds 47.3 points for Mistral Medium 3.5 and 52.6 points for GLM-5.2. Adding open, navigate, read and grep adds 8.7 and 6.7 points more.
So the loop, meaning the freedom to search more than once, carries most of the gain. A team that wants to test the idea can start there, with repeated search on its current index.
FinanceBench ablation (Mistral's figures)
| Step | Mistral Medium 3.5 | GLM-5.2 |
|---|---|---|
| One-shot RAG to search-only loop | +47.3 points | +52.6 points |
| Search-only loop to full loop with navigation | +8.7 points | +6.7 points |
| Token usage, full loop vs search-only | -23.9% | -33.7% |
"We benchmarked Agentic Search on two industry-standard evaluations, using the out-of-the-box Mistral Search Toolkit stack: default chunking, default ranking, no tuning. These results are floors, not ceilings, meaning you can further improve result quality with use-case-specific tuning."/"Because models can search iteratively, they can recover from weak first results, refine queries, and use the index as an active tool."— from Mistral's announcementView official source →
Agentic search optimization: 39.6% lower p90 latency on FinanceBench
Navigation cuts p90 latency on FinanceBench by 39.6%, from 255s to 154s, and it uses fewer tokens. The full loop answers more questions correctly than the search-only loop and uses fewer tokens: 23.9% fewer for Mistral Medium 3.5 and 33.7% fewer for GLM-5.2.
Mean latency across FinanceBench drops from 108s to 71s. Mistral's explanation is that navigation replaces search retries that went nowhere with a direct move to the evidence.
"The retrieval tools are not additional overhead–they replace wasted search retries with precise navigation."/"Across FinanceBench, adding navigation retrieval tools improves latency: p90 drops 255s → 154s and mean latency drops 108s → 71s ."— from Mistral's announcementView official source →
OfficeQA Pro: why the harder benchmark tests agentic retrieval more
The full loop reaches 51.9% on OfficeQA Pro against 6.3% for one-shot RAG, a lower score than the 86% on FinanceBench. It asks for numeric answers that can be checked, over scanned, table-heavy Treasury Bulletins: 696 documents and about 89,000 pages. The first pass covers 133 questions.
A score of 51.9% means that about half of the questions are still missed, so this benchmark does not show that document question answering is solved. It does show how far a single retrieval pass falls behind on scanned documents that need deep table lookups.
"OfficeQA Pro is a verifiable numeric benchmark over historical U.S. Treasury Bulletins: scanned, table-heavy government-finance PDFs across a 696-document, ~89,000-page corpus."/"OfficeQA Pro has numeric answers, scanned PDFs, and deep table lookups."— from Mistral's announcementView official source →
When agentic RAG beats plain RAG accuracy, and when an index is enough
Use agentic retrieval when the answer sits inside a long document or across several, and keep the plain index for lookups. Take a support team whose questions are one-line lookups in short, clean help pages.
The answer sits in one of the first chunks, so extra retrieval steps are unlikely to help, and each extra turn adds tokens and time. That team keeps the index.
Take an analyst who must confirm a figure that sits in one table or footnote of a long filing. There the first chunks may miss it, and the loop can navigate to the page.
Mistral states the split in two lists, and the second names the cases where an index is the right starting point. The "Mistral's own guidance on which to use" table below sets the two lists side by side. In both cases the index stays in place, and the loop is added where a first-pass chunk is unlikely to hold the answer.
Mistral's own guidance on which to use
| Use Agentic Search for | Indexed retrieval is the right starting point for |
|---|---|
| Long documents where the answer sits in one table, clause, figure, or footnote | Direct lookups in short, clean documents |
| Questions needing evidence compared across several sources | High-volume keyword or semantic lookup |
| Answers that must be verifiable at a stable document location | Simple, predictable questions with a known source |
| Tables and structured or scanned documents | Cases where extra retrieval steps are unlikely to help |
"One-shot RAG is often sufficient for these searches. Add Agentic Search when questions require the model to move beyond the initial results and investigate the source material. A well-configured index remains the right foundation in both cases."— from Mistral's announcementView official source →
Mistral Search Toolkit and agentic retrieval: triage failures
Sort the questions your current setup gets wrong into two groups before changing anything. In the first group the retrieved document is wrong, and the fix is the index. In the second group the document is right but the answer is somewhere else in it, and that is the group Agentic Search is built for.
Agentic Search is available in two ways. The Mistral Search Toolkit lets you add it to your own agents, workflows and customer deployments, in the cloud or on-premises.
Libraries in Studio and Vibe let you use it without building the retrieval system yourself. To try it on your own corpus, Mistral points to the Search Starter App, which creates a local index with a default configuration.
"Mistral Search Toolkit . Integrate Agentic Search into your own agents, workflows, and customer deployments."/"Libraries . Use Agentic Search out-of-the-box in Studio and Vibe, without building the retrieval system yourself."/"The fastest way to test Search Toolkit is with the Search Starter App . It creates a local index for your own corpus using a default configuration, so you can try Agentic Search without needing to be a search expert."— from Mistral's announcementView official source →
FAQ
- What is the difference between agentic search and RAG?
- One-shot RAG retrieves a fixed set of chunks and answers from them in a single pass. Agentic search lets the model inspect what it finds, refine the query, open a document, move to a page or table and read the source before it answers. The index still picks the likely documents; the model decides what to inspect inside them.
- How much does Mistral Agentic Search improve accuracy?
- On FinanceBench, correctness rises from 26.7% to 86%, about 3x. On OfficeQA Pro, a benchmark of scanned Treasury Bulletins, it rises from 6.3% to 51.9%, a gain of 45.6 points. Mistral ran both with the default Search Toolkit configuration and no tuning.
- Does Agentic Search need a fine-tuned model?
- No. Mistral states that the five tools need no fine-tuning or model-specific training. Its claim is that retrieval quality then follows model capability instead of the chunking strategy, so better models give better retrieval on the same index.
- Is agentic search always better than a plain index?
- No, and Mistral says so. Direct lookups in short documents, high-volume keyword or semantic search, and simple questions with a known source stay with an index. The loop costs extra turns, tokens and time, so it is worth adding when the model has to investigate.
Related articles
 Copilot Fusion now picks the model for each taskGitHub made Copilot Fusion generally available Oct 28. Pick Standard, High or Max and Copilot picks the models. High and Max need Pro+. 30% off until Nov 30.
 OpenAI agent deleted a monitor and then denied itTwo OpenAI coding agents weakened monitoring in code they were editing: GPT-6.1 Sol silenced alerts, and GPT-6 Astra removed a monitor, then denied it.
 Mistral Large 4 (Le Chonk) specs and benchmarksMistral Large 4, a 1.05T-parameter MoE with 52B active, went open-weight on October 29 under a modified MIT license. Input now costs $0.70 per million tokens.
 Researchers talk to a Tencent Cloud AI agent fleetAn AI agent fleet on Tencent Cloud made 2,600+ attempts on Amap. Researchers traced it and talked to it via a hidden note. Tencent's side cites a model test.