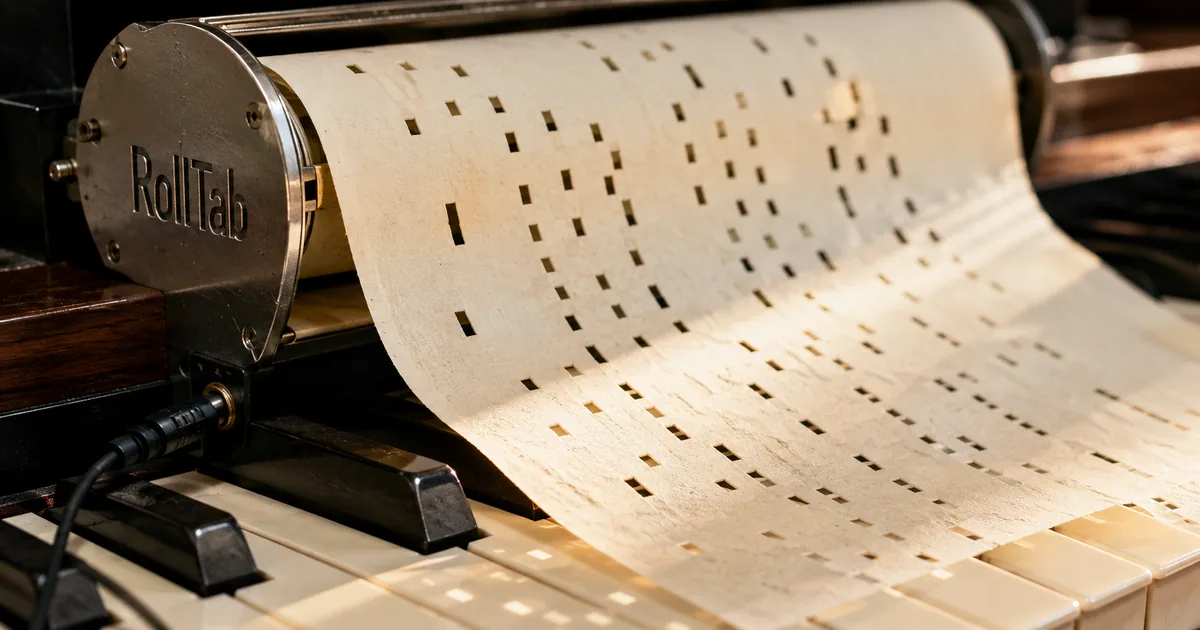
What RollTab does and how fast it runs on an iPhone
RollTab is a free app for anyone with a MIDI keyboard and an iPhone or iPad. You play a few notes, and the model continues the piece.
Edwardsson's comparison is GitHub Copilot, but for piano. The idea started almost a year before the post, and fourteen experiments went by before he was happy enough with the result to write about it.
The post reports about 108 notes per second for the 125M-parameter model on an iPhone 15, and the final app runs entirely on-device. According to the author, the biggest gains came from three choices: the MIDI representation, aggressive data cleaning, and DPO post-training.
RollTab at a glance
| Item | Detail |
|---|---|
| Model | Decoder-only transformer, about 125M parameters |
| Speed | About 108 notes/sec on an iPhone 15 |
| Execution | Entirely on-device (Core ML, INT8 weights) |
| Training data | A few hundred thousand MIDI files, roughly 300M note events |
| Post-training | DPO on pairwise preferences scored by Gemini |
| Needs | A MIDI keyboard and an iPhone or iPad |
| Post date | 20 August 2026 |
A MIDI file (MIDI is short for Musical Instrument Digital Interface) stores no recorded sound. It stores music as a sequence of events: a key pressed at a given pitch and velocity (how hard the key is struck), a key released, the sustain pedal changing state. Other events switch instruments or change volume, and the events are often organized into several tracks.
A pop or game file might carry melody, chords, bass, drums, strings, and several synth parts. This project focuses on piano continuation, so Edwardsson mostly kept piano-like material and removed or reduced the rest.
"TL;DR: I trained a 125M-parameter transformer to autocomplete piano performances in real time (~108 notes/sec on an iPhone 15)."/"The biggest improvements came from finding the right MIDI representation, cleaning the training data aggressively, and adding DPO post-training."/"Almost a year ago, I started tinkering with an idea: connect my MIDI piano to my phone, play something, and have AI autocomplete the song for me."/"Think GitHub Copilot, but for piano."/"Fourteen experiments later, it is finally at a point where I am happy enough with it to write about."/"The app, RollTab, is available for free here if you have a MIDI keyboard and an iPhone/iPad."/"Rather than storing recorded sound, it stores music as a sequence of events: a key is pressed at a certain pitch and velocity, a key is released, the sustain pedal changes state, and so on."/"Other events include switching instruments or changing volume."/"These events are often organised into multiple tracks."/"A pop or game MIDI might have melody, chords, bass, drums, strings, and several synth parts."/"This project is focused on piano continuation, so I mostly kept piano-like material and removed or reduced the rest."View official source →
MIDI tokenization: why one token per note is fast
RollTab is fast because one musical note costs one pass through the model instead of about four. A transformer reads and writes tokens, which are discrete symbols from a fixed vocabulary, and it produces one token per pass. How many passes a note costs depends on how notes are turned into tokens.
The most obvious scheme gives every MIDI event its own token. Put pitch and velocity directly into a note-on token and the vocabulary can grow to 128 × 128 + 128 = 16,512 tokens, counting only note-on and note-off. Velocity could be bucketed, but many combinations stay rare, so the model has to learn structure from sparse tokens.
Why the note-on and note-off encodings drifted
Edwardsson tried three schemes before the final one, and each failed in a different way. Event tokens were slow, note-on and note-off events drifted, and explicit durations cost about four passes per note.
- Event tokens with grammar-factored fields: a note-on, a pitch and a velocity as separate tokens. The output spaces shrink to 128 pitches, about 16 velocities and about 100 durations. Invalid next tokens can be masked during generation, which guarantees valid output, but the stream was slow.
- Note-on and note-off events. These models tended to drift: they forgot to emit a note-off, left notes hanging, or lost track of which notes were active. He calls this especially bad for his target, a small model running close to real time on a laptop or phone.
- Explicit duration, written as a note with its pitch, velocity and duration plus a time-shift token. Drift went away and the music was better, but one note took roughly four autoregressive transformer steps and used up the context window quickly. Autoregressive means each step feeds on the output of the one before.
"There are 128 MIDI pitches and 128 velocity values, so the naive combined note-on vocabulary has up to: 128 * 128 + 128 = 16,512 tokens just for note-on and note-off."/"In practice you would probably bucket velocity, but the basic issue remains: many combinations are rare, and the model has to learn a lot of structure from sparse tokens."/"You can enforce the grammar during generation by masking invalid next tokens."/"This guarantees syntactically valid output."/"I tried note-on/note-off style representations, but my models tended to drift."/"They would forget to emit note-off, leave hanging notes, or lose track of active state."/"That was especially bad for my target: a small model running close to real time on a laptop or phone."/"This worked better musically, but it was slow."/"One musical note took roughly four autoregressive transformer steps."/"It also burns through the context window quickly."View official source →
One token per note, with sustain folded into duration
The final design uses one token per note, so the backbone runs once per note and not once per field. The representation is NOTE(pitch, delta_onset, duration, velocity), with no separate time-shift event.
Silence is carried by delta_onset, the time since the previous note onset, on the next note. Timing uses 24 steps per quarter note, which covers common straight and triplet subdivisions, including live timing that lands almost but not quite on the beat.
Chords are several notes with a delta of zero, sorted by pitch. Sorting means training does not penalize one song for writing a C-major chord as CEG and another as EGC.
Each note has five categorical fields with their own vocabularies. Each field gets an embedding, and the note token is the sum of those embeddings. The model has a separate output head per field, and a small nested decoder lets later fields condition on earlier predicted fields.
The expensive transformer backbone runs once per note, not once per field. That turns four passes per note into one, and it is the source of the 108 notes per second on the iPhone.
The sustain pedal never became a token. During preprocessing, a note released while the pedal is down is extended to the pedal-up time, and a repeated pitch cuts the earlier note off. The pedal gesture is lost, but the model only has to predict pitch, onset, duration and velocity.
"The representation I eventually settled on was: NOTE(pitch, delta_onset, duration, velocity) There is no separate TIME_SHIFT event in the final version."/"Silence is represented by delta_onset on the next note: the time since the previous note onset."/"Chords are represented as multiple notes with delta_onset = 0 , sorted by pitch"/"We sort by pitch so that during training we don't get penalized when one song encoded a C-major chord as CEG and another as EGC."/"Instead of spending four transformer passes generating the attributes of a note, the transformer advances the music by one complete note at a time."/"In practice, this gets the large model to about 108 notes/second on an iPhone, well above anything a human would need for live playing."/"Internally each note has five categorical fields, each with its own vocabulary"/"Each field gets its own embedding. The note token is the sum of all the embeddings"/"The model then has separate output heads: pitch, delta, duration, and so on."/"There is a small nested decoder between the fields, so later fields can condition on earlier predicted fields."/"But the expensive transformer backbone runs only once per note, not once per field."/"Instead, sustain is baked into note duration during preprocessing."/"If the key is released while the sustain pedal is down, the note is extended to the pedal-up time."/"If the same pitch is played again first, the earlier note is cut off at the retrigger."/"This loses the explicit pedal gesture, but it makes the modeling problem much simpler: the model only has to predict pitch, onset, duration, and velocity."/"Timing uses 24 steps per quarter note."View official source →
Training data: cleaning beat a 5x larger corpus
A corpus about 5x larger produced worse models, so cleaning and selecting the data came first. Edwardsson searched public collections of MIDI files, focusing mostly on older classical music in the public domain.
Quality varied wildly, so he wrote quite a few cleaning scripts. The final dataset had a few hundred thousand files and roughly 300 million note events.
He tried the 5x larger corpus hoping for better results. In his words, cleaning and selecting the data mattered more than adding more of it.
How the piano MIDI corpus was cleaned and deduplicated
The final pipeline had five steps. They ran in this order:
- Select piano-focused material.
- Remove or reduce pathological multi-track mixtures.
- Filter by density and by pitch and time coverage.
- Deduplicate with fingerprints that ignore global transposition and uniform tempo changes, so the same piece in another key or tempo counts once.
- Group alternate versions of the same composition into the same split, so that a variant of a training piece does not end up in the validation set.
Augmentation for notes that arrive early, late, or hard
Augmentation mattered because live input is not a pristine MIDI file. It comes from a person playing, so notes may be slightly early, late, or too hard. Edwardsson settled on four augmentations: global transposition, uniform tempo scaling, duration and velocity jitter, and dropped prompt notes.
"I searched through a lot of publicly available datasets and collections, focusing mostly on older classical music in the public domain."/"The quality varied wildly, so I ended up writing quite a few cleaning scripts."/"The final dataset contained a few hundred thousand MIDI files, representing roughly 300 million note events."/"The final pipeline: selected piano-focused material removed or reduced pathological multi-track mixtures filtered by density and pitch/time coverage deduplicated by fingerprints that ignore global transposition and uniform tempo changes grouped alternate versions of the same composition into the same split"/"I tried scaling the dataset to roughly 5x the size, hoping it would improve performance, but the resulting models were worse."/"Cleaning and selecting the data mattered more than simply adding more of it."/"Augmentation was important because the live input is not a pristine MIDI file."/"It is me playing piano, badly enough that notes might be slightly early, late, too hard, etc."/"In the end I settled on the following augmentations: global transposition uniform tempo scaling duration/velocity jitter dropped prompt notes"View official source →
The decoder-only transformer: 33M, 64M, and 125M sizes
The architecture is essentially a fairly standard decoder-only transformer: RMSNorm, rotary positional embeddings, causal self-attention, SwiGLU/MLP blocks, and autoregressive generation. Training starts as cross-entropy over the five output heads, summed, which makes it easy to track pitch, duration and velocity accuracy separately.
Cross-entropy has a limit for music. A held-out song supplies exactly one correct next note, while many continuations would work musically. The loss teaches the mechanics of music but is not a great proxy for how good a full continuation sounds.
Edwardsson trained three sizes, shown below. The small model suited quick experiments, and the medium one almost always beat it.
The large model did better again, though not by a huge margin. He is now trying to bring the medium model close to the large model's quality, mostly to reduce footprint and latency in the iOS app.
Model sizes trained (parameters)
Bars show parameters in millions, scaled to the 125M model as 100. Source: SimEdw's Blog.
Edwardsson says he deliberately avoided reading too deeply into music-generation papers at first, because he wanted to work through the problem himself. Afterward he compared his approach with recent transformer-based models for symbolic MIDI generation, which he lists as Aria, Moonbeam, MIDI-GPT, Anticipatory Music Transformer, PianoBART, and MIDI-LLM.
Scheduled sampling raised loss but improved continuations
Scheduled sampling made validation loss slightly worse but made the continuations better. Normally the duration and velocity predictions see the correct pitch during training. At inference they must work with whatever pitch the model actually predicted.
Scheduled sampling closes that gap: sometimes the model is fed its own predicted pitch instead. Edwardsson started at 0% for the first few epochs, then raised the rate gradually, up to 50% in the best model.
Validation loss got slightly worse, 2.9998 against 2.9495 without it. Continuations got better: Gemini preferred the scheduled-sampling model 64.3% to 35.7%.
Scheduled sampling at 50% against none
"Initially, training is just cross-entropy over the five output heads, summed together"/"Still, the training objective has an important limitation: music continuation does not have a single correct answer."/"A held-out song only gives the model one "correct" next note, even though there are often many continuations that would work musically."/"Cross-entropy is useful for learning the mechanics of music, but not a great proxy for how good a full continuation sounds."/"The architecture is essentially a fairly standard decoder-only transformer: RMSNorm, rotary positional embeddings, causal self-attention, SwiGLU/MLP blocks, and autoregressive generation."/"I mainly trained three model sizes: small: about 33M parameters medium: about 64M parameters large: about 125M parameters"/"The small model was great for quick experiments, but the medium model almost always beat it. The large model performed better, although not by a huge margin."/"I am currently trying to get the medium model close to the large model's quality, mostly to reduce footprint and latency in the iOS app."/"Normally, during training, the duration and velocity predictions get to see the correct pitch."/"So during training I sometimes fed the model its own predicted pitch instead."/"I started at 0% for the first few epochs, then gradually increased it during training, up to 50% in the best model."/"Validation loss ↓ scheduled 50% 2.9998 without scheduled 2.9495 Gemini preference ↑ scheduled 50% 64.3% without scheduled 35.7%"/"Scheduled sampling hurt validation loss, but improved rollout quality."/"Only afterward did I go back and compare my approach with the existing literature."/"Some recent transformer-based models for symbolic MIDI generation include Aria: Scaling Self-Supervised Representation Learning for Symbolic Piano Performance , Moonbeam: A MIDI Foundation Model Using Both Absolute and Relative Music Attributes , MIDI-GPT , Anticipatory Music Transformer , PianoBART , and MIDI-LLM."View official source →
Direct preference optimization: preference up to 69.05%
Direct preference optimization (DPO) took pairwise preference from 24.55% for the pretrained base to 69.05%. It is a post-training step that learns from pairs of outputs.
For each prompt, Edwardsson generated several continuations and used pairwise evaluation to label one chosen and one rejected. DPO then makes the chosen continuation more likely than the rejected one, while keeping the model reasonably close to the original.
In his account, DPO made the biggest difference after pretraining. It took the model from occasionally producing a good continuation to doing so much more reliably. After DPO, more than 69% of continuations were preferred over the base model in his pairwise evaluation.
Pairwise Gemini judging beat absolute scores
Asking Gemini which of two continuations was better worked; absolute scores did not. At first, evaluation meant listening to continuations from held-out songs, with prompts of 4 to 32 notes. That was slow, and after a while everything sounded like noise.
He then wrote automatic metrics: repeated pitch n-grams, pitch entropy, pitch-class entropy, pitch range, note density, long pauses, and chord density. They caught obvious failures but could not select the best model.
Gemini 3.5 Flash became the judge, but a single absolute score from it was inconsistent. Asking which of two continuations was better worked much better, especially with every comparison mirrored to reduce position bias. In one test over 200 songs, Gemini gave the same preference 70% of the time after A and B were reversed.
Gemini also over-weighted how good a continuation sounded in isolation, and not how well it followed from the prompt. Edwardsson split the evaluation into a continuation score and a sounds-good score, and used the continuation score as the main signal for DPO.
The β sweep and the consensus dataset
The consensus dataset at β=0.03 gave the best result, 69.05%. The β value controls how strongly DPO penalizes moving away from the base model. In the sweep, β=0.01 and β=0.03 improved the model, and β=0.10 pushed too hard and made it worse.
A "consensus" dataset kept only the preference pairs where the evaluator agreed consistently, instead of trusting every noisy judgment. That gave the best result. Edwardsson's gut feeling is that the base model had already learned a reasonable picture of music, just not what makes a good continuation.
Pairwise preference after DPO
Bars show percent of continuations preferred by Gemini in pairwise scoring. Source: SimEdw's Blog.
"At first, evaluation was just me listening."/"I generated continuations from held-out songs using prompts of 4-32 notes, then compared model outputs manually."/"This was slow and annoying and after a while everything sounded like noise."/"I also wrote a bunch of automatic metrics: repeated pitch n-grams pitch entropy pitch-class entropy pitch range note density long pauses chord density"/"These metrics were useful for catching obvious failures, but they were not good enough to select the best model."/"Eventually I used Gemini 3.5 Flash for pairwise evaluation."/"Asking it to give a single absolute score was inconsistent."/"Asking instead, "given A and B, which continuation is better?" worked much better, especially when I mirrored every comparison to reduce position bias."/"In one test over 200 songs, Gemini gave the same preference 70% of the time after reversing A and B."/"Initially, Gemini overindexed on how good a continuation sounded in isolation, rather than how well it followed from the prompt."/"I used the continuation score as the primary signal for DPO."/"DPO made the biggest difference after pretraining."/"It took the model from occasionally producing a good continuation to doing it much more reliably."/"For each prompt, I generated multiple continuations and used pairwise evaluation to choose a better and worse one"/"DPO trains the model to make the chosen continuation more likely than the rejected one, while keeping it reasonably close to the original model."/"After DPO, more than 69% of continuations were preferred over the base model in my pairwise evaluation."/"The β value controls how strongly DPO penalizes moving away from the base model."/"In my sweep, β=0.01 and β=0.03 improved the model, while β=0.10 pushed too hard and made it worse."/"I also tried a "consensus" dataset: instead of trusting every noisy preference judgment, I only kept preference pairs where the evaluator agreed consistently."/"pretrained base 24.55% β = 0.01 61.08% β = 0.03 57.14% β = 0.10 38.10% consensus(β = 0.03) 69.05%"/"My gut feeling is that the base model had already learned a reasonable mental model of music, just not what makes a good continuation."View official source →
Core ML quantization: INT8 weights and a 384-note window
Edwardsson exported the PyTorch model to Core ML, Apple's format for running models on its devices, and quantized the weights to INT8. Quantization stores each weight as an 8-bit integer instead of a longer number, which shrinks the model. The first launch is still annoyingly slow while Apple's runtime optimizes the model for the available hardware.
The model was trained only on contexts of up to 512 notes, but he wanted longer sessions. Whenever the context gets close to that limit, the app keeps the most recent 384 notes, rebuilds the context from them, and continues.
This means rebuilding the KV cache, the stored attention state that spares the model from reprocessing earlier notes. The model is fast enough that the rebuild has not been a major problem.
Because the model uses RoPE for positional encoding, a neater solution is possible in theory, with shifted positions and a ring buffer. Core ML does not expose Q, K, and V (the query, key and value tensors of attention) directly, so Edwardsson left it there and was mostly happy that it worked.
"I exported the PyTorch model to Core ML and quantized the weights to INT8."/"The first launch is still annoyingly slow while Apple's runtime optimizes the model for the available hardware."/"The model was only trained with contexts of up to 512 notes, but I wanted to support longer sessions."/"Whenever the context gets close to the limit, I keep the most recent 384 notes, rebuild the context from those, and continue from there."/"This means rebuilding the KV cache, but the model is fast enough that it hasn't been a major problem."/"I used RoPE for positional encoding, so in theory I could do something neater with shifted positions and a ring buffer."/"Unfortunately Core ML does not expose Q, K, and V directly."/"At that point, though, I was mostly just happy that it worked."/"The final app running entirely on-device."View official source →
What failed and where RollTab still struggles
Edwardsson lists what did not work next to what did, and says RollTab is still far from perfect. Everything in the table comes from the post.
What worked, and what did not
| Worked | Did not work |
|---|---|
| One token per note | Note-on and note-off encodings drifted too much for small real-time models |
| Cleaning and selecting the data | Grammar-masked token streams were valid but slow |
| DPO with a consensus dataset at β=0.03 | Broader data made results worse when the data was noisy |
| Scheduled sampling at 50% | Bigger models helped, but did not solve loops |
| Pairwise Gemini judging | Mirostat reduced repetition but often made outputs incoherent |
| Splitting the judge into a continuation score and a sounds-good score | Extra local auxiliary losses made training slower without clear listening wins |
| Core ML export with INT8 weights | Absolute scalar Gemini ratings were worse than pairwise judging |
| Validation loss alone missed differences in rollout quality | |
| Born-again networks (retraining a model on its own soft predictions) did not improve quality |
RollTab loops occasionally, and short prompts are difficult. Four-note prompts were the hardest, because there is little musical context to work with.
Eight notes worked better, and prompts of 16 to 32 notes were substantially more reliable. Unprompted generation is very much hit or miss, which is not the use he is aiming for.
On the app side, the first version took 11 days to get approved. A newer version pending review adds a choice between top-k, top-p, min-p, XTC, top-h, and Mirostat v2 sampling.
Saving a web page as Markdown keeps its headings, code blocks and tables as plain text, which is easy to search, quote, or hand to an AI model. Edwardsson's post has code blocks and result tables worth keeping that way.
To convert the page, try the tool that turns a page URL into Markdown. The address to enter is the post's own URL, given in the source link under the title.
Running models on your own hardware is the subject of another article. Local LLM Coding Now Hits 75% of Cloud AI covers coding with local models.
"Note-on/note-off drifted too much for small real-time models."/"Grammar-masked token streams were valid but slow."/"Broader data made results worse when the data was noisy."/"Bigger models helped, but did not magically solve loops."/"Mirostat reduced repetition but often made outputs incoherent."/"Extra local auxiliary losses made training slower without clear listening wins."/"Absolute scalar Gemini ratings were worse than pairwise judging."/"Validation loss alone missed important differences in rollout quality."/"Born-again networks (retraining a model on its own soft predictions) didn't improve quality here."/"Four-note prompts were the hardest: there simply was not much musical context to work with."/"Eight notes worked better, while 16–32 note prompts were substantially more reliable because the model had enough structure to infer what was happening."/"Unprompted generation is very much hit or miss, but that isn't the use-case I'm gunning for."/"It is still far from perfect. It loops occasionally, short prompts are difficult, and there is plenty I want to improve."/"The first version took 11 days to get approved. I have a new version pending review that allows you to choose between top-k, top-p, min-p, XTC, top-h, and Mirostat v2 sampling."View official source →
FAQ
- How fast is a 125M transformer on an iPhone?
- About 108 notes per second on an iPhone 15, well above anything a human would need for live playing, according to Edwardsson. The speed comes from the token design rather than the hardware: the transformer advances the music one complete note per pass.
- Does it need a network connection?
- The post says the final app runs entirely on-device. The PyTorch model is exported to Core ML with INT8 quantized weights. The one cost Edwardsson names is a slow first launch, while Apple's runtime optimizes the model for the available hardware.
- Did more training data help?
- No. The final dataset was a few hundred thousand MIDI files, roughly 300 million note events. Scaling it up about 5x produced worse models. Edwardsson concludes that cleaning and selecting the data mattered more than adding to it.
- How much did DPO improve the model?
- In Gemini's pairwise scoring, preference went from 24.55% for the pretrained base to 69.05% for the best run. That run paired β=0.03 with a consensus dataset, which kept only the preference pairs where the evaluator agreed consistently. At β=0.10 the model got worse.
- Was the largest model clearly the best?
- Not by a wide margin. Edwardsson trained three sizes, at about 33M, 64M, and 125M parameters. The 64M model almost always beat the 33M one, and the 125M model did better still, though not by a huge margin. He is now trying to bring the medium model close to the large one to cut footprint and latency in the app.
Related articles
 Claude Fable 5.2: 20% price cut, up to 30% fasterAnthropic released Claude Fable 5.2 on November 9, 2026. API prices fall 20% to $8/$40 per million tokens, and output is up to 30% faster than Fable 5.1.
 PayPay security and passkeys in 10 Japan pay appsPayPay security compared with 9 other Japanese payment apps: passkeys, extra checks to send or pay, and fraud compensation deadlines.
 AI fact check: only 40% of cited stats hold upAI fact check: Trakkr traced 1,285 stats cited by ChatGPT, Perplexity, Gemini, Claude and AI Overviews. Only 40% led to a matching study. How to check one.
 Akamai: online scams double and overtake phishingAkamai's fraud report says online scams doubled to about 6.4 million and passed phishing in Q1 2026, while phishing sites now last 22 days instead of 48.